Terminal X matches senior investor judgment 88.6% with GPT‑6.1
Terminal X’s Eval Agent grades outputs against a 54-criterion rubric, catching 25% more deviances from a fund’s mandate with GPT‑6.1 Sol.
25%
Higher detection rate when agent answers fall outside a fund’s mandate on GPT‑6.1 Sol vs. next-best model
$2.4M
Annualized savings for one customer on due diligence and investment workflows
+220bps
Higher agent agreement with human reviewers on GPT‑6.1 Sol vs. next-best model
30%
Lower cost per query with GPT‑6.1 Sol vs. next-best model
An investment firm’s edge is built deal by deal, but the judgment behind each decision usually lives in the heads of a few senior investors. When they leave, the firm takes on what Terminal X(opens in a new window) calls memory debt: the firm may keep the documents, but it loses the reasoning.
Terminal X’s Capital Memory operating system is designed to pay that debt down. The company’s forward-deployed engineers, former finance and investment professionals at JPMorgan and Blackstone, sit with each customer’s investment teams, design the firm’s agentic architecture, and encode how the firm invests into agents the firm owns, deployed on-premise or in its own cloud.
OpenAI models, including GPT‑6.1 Sol and GPT‑6 Luna, handle the reasoning inside those agents. And Terminal X’s Eval Agent grades the agents’ output against the firm’s standards. GPT‑6.1 Sol helped the Eval Agent catch about 25% more recommendations that strayed from a fund’s mandate and ran the same workflows at approximately 30% lower cost per query than the next-best model.
“GPT-6.1 Sol’s long-context reasoning and token efficiency allow us to build deeper evaluation pipelines. This helps our Eval Agents make investment judgment measurable and auditable.”
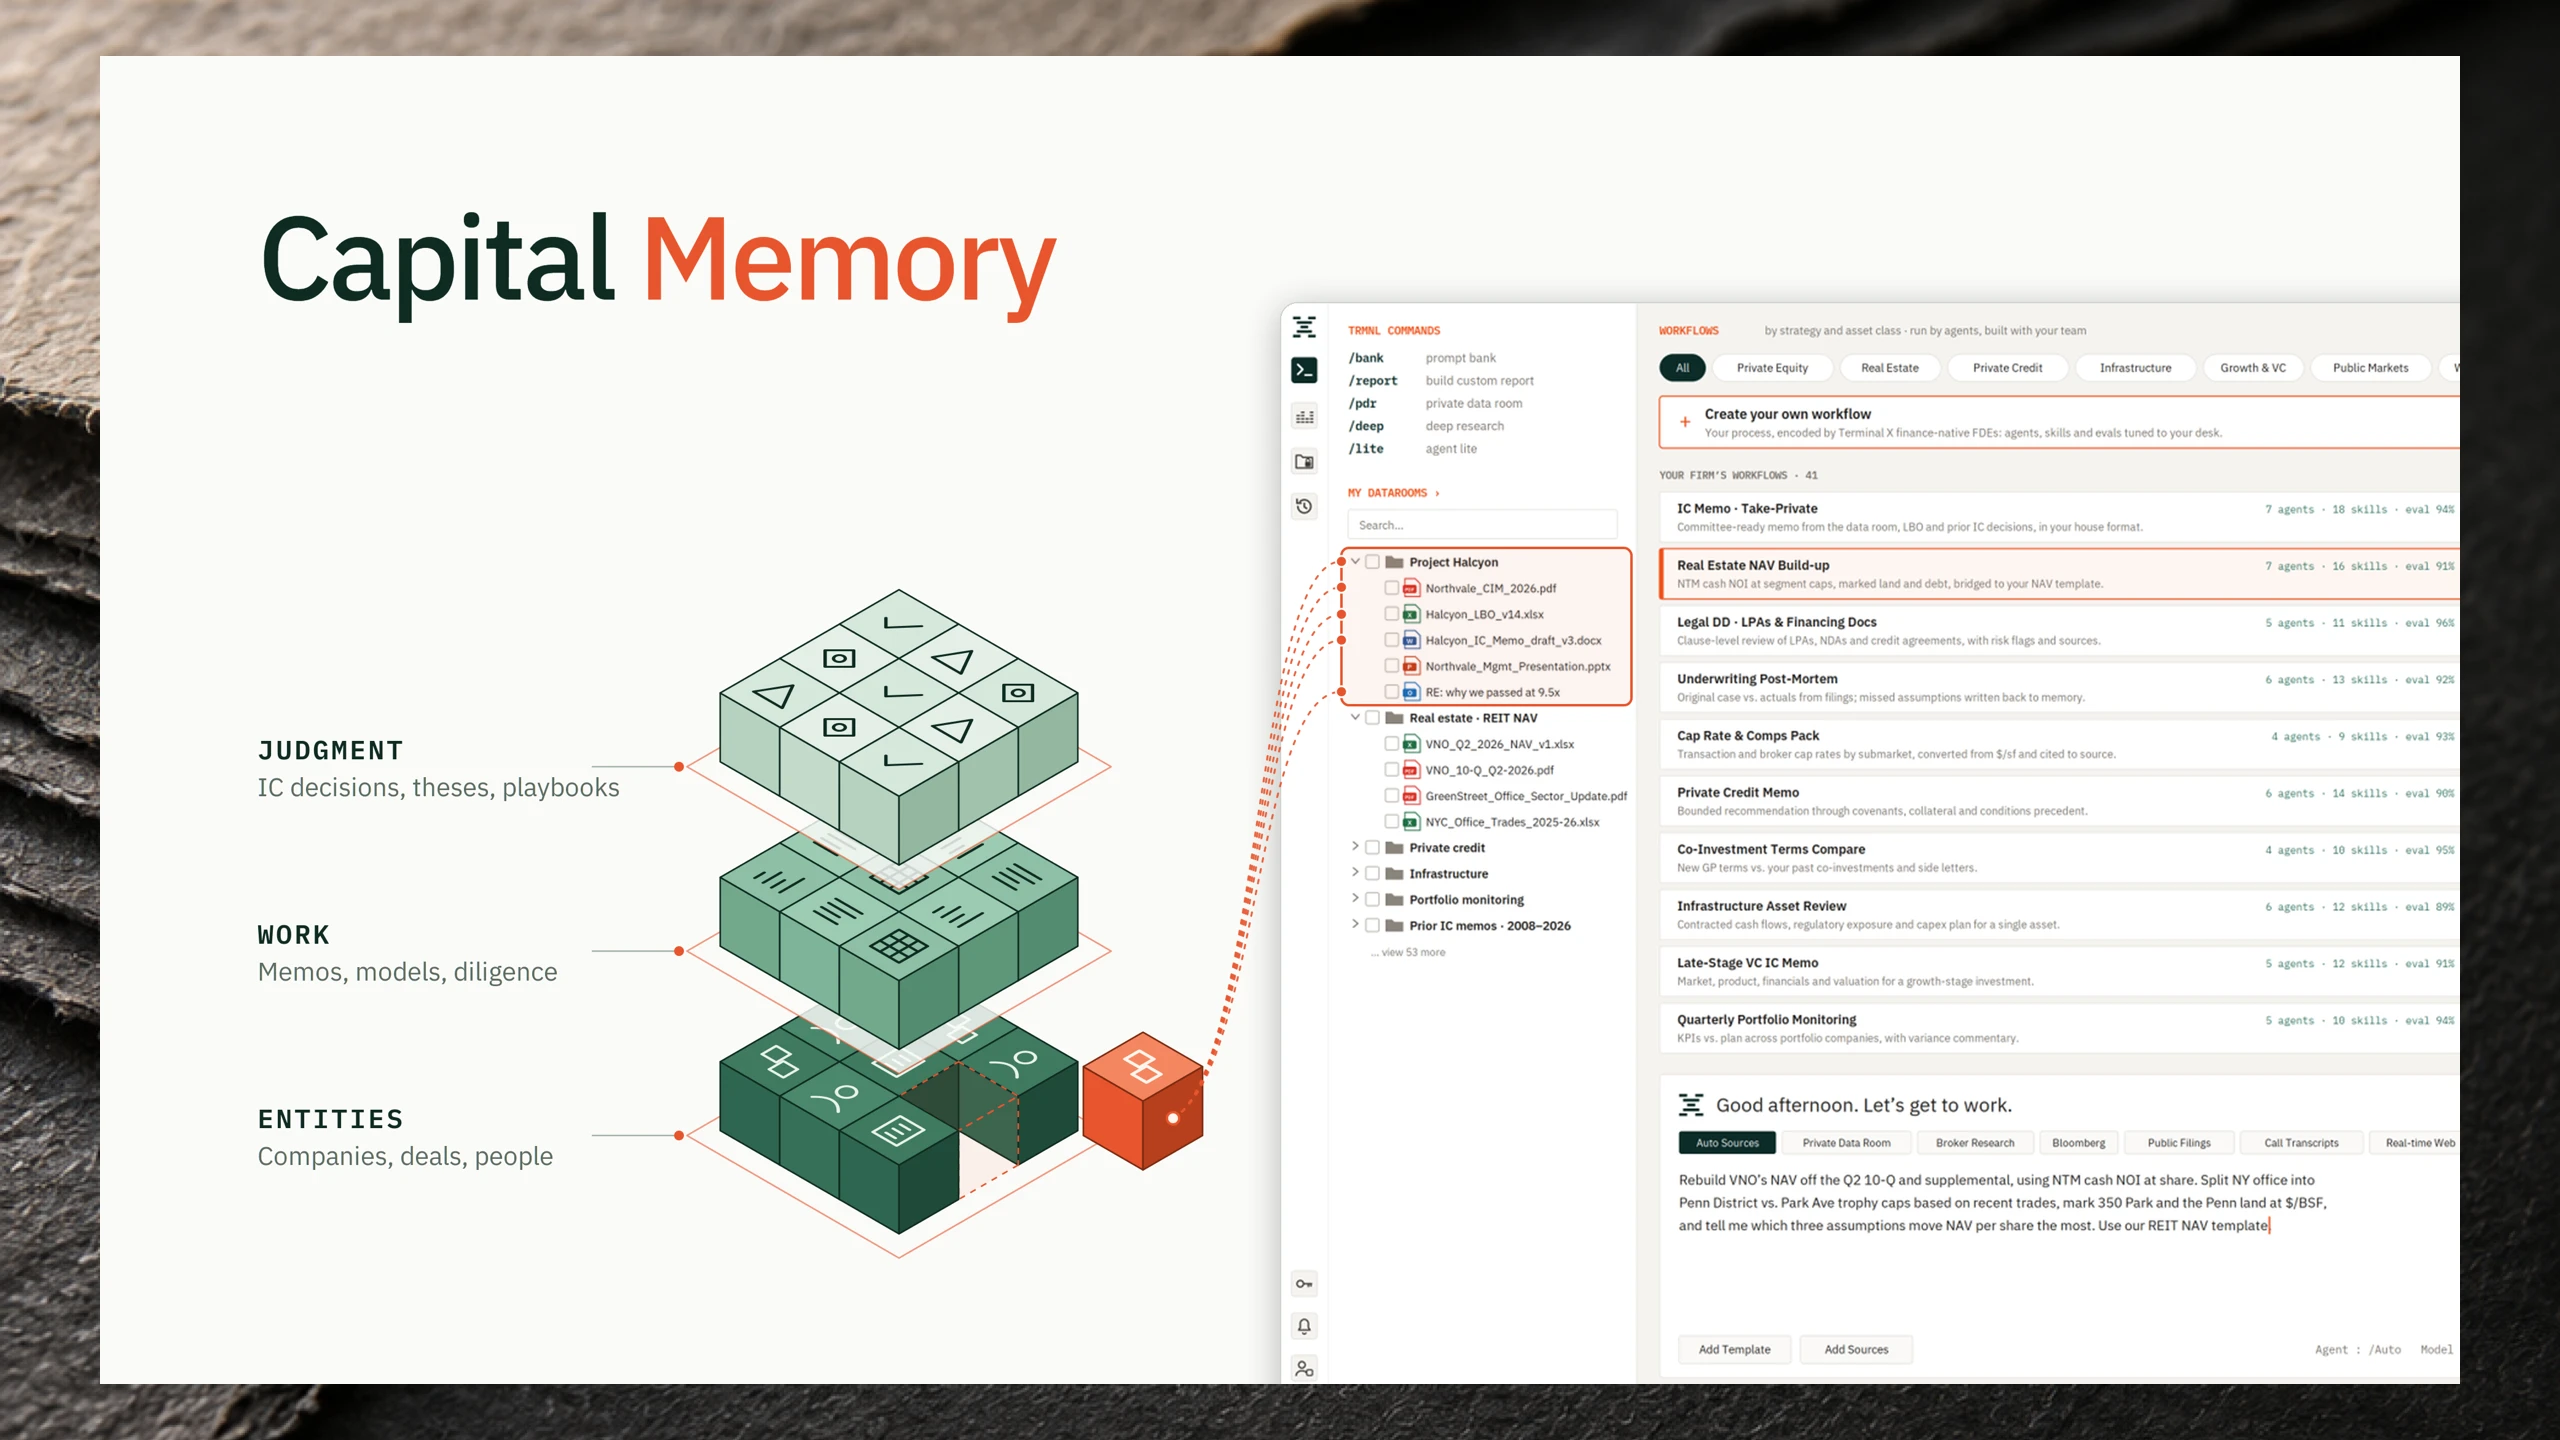
For each customer, Terminal X builds agents designed to invest the way the firm’s best investors do. Terminal X engineers spend weeks onsite with the customer, reverse-engineering the firm’s trusted memos and capturing processes that were never written down, such as how the credit desk screens a borrower or which sources the co-investment team pulls before a memo.
Next, those processes are encoded in hundreds of agents, customized by asset class and strategy, with sub-agents for each investment stage. GPT‑6.1 Sol handles the stages that require judgment and a huge context window: synthesizing the investment thesis, identifying key considerations, and assessing fit with the firm’s mandate. GPT‑6 Luna runs the high-volume steps where token efficiency matters more than depth.
The agents work inside each firm’s private data room, a dedicated environment for enterprises to share and manage sensitive investment data. The agents process documents in English, Korean, Japanese, and Chinese, and store what they learn as a firm Memory: a versioned record of how one desk makes one kind of decision, including its past analyses, committee decisions, workflow instructions, and house views.
Engineers turn each Memory into a repeatable workflow on Terminal X’s platform, where every production query is auditable with its full trail: the steps taken, sources retrieved, model used, and the reasoning.
According to Terminal X, customers see significant savings as a result of this approach, including one private equity firm that reported $2.4 million in annualized savings from automated due diligence and investment memo workflows.
To check agents’ answers against the firm’s own standard, Terminal X built an Eval Agent. It’s an orchestrated workflow on GPT‑6.1 Sol and other OpenAI models designed to read every agent output the way a VP reads an analyst’s work.
The Eval Agent checks each output against a 54-criterion rubric. It asks: Are the numbers, comps, consensus figures, and quotes pulled from the right sources? Does the narrative hold? Does the recommendation tie to the house view?
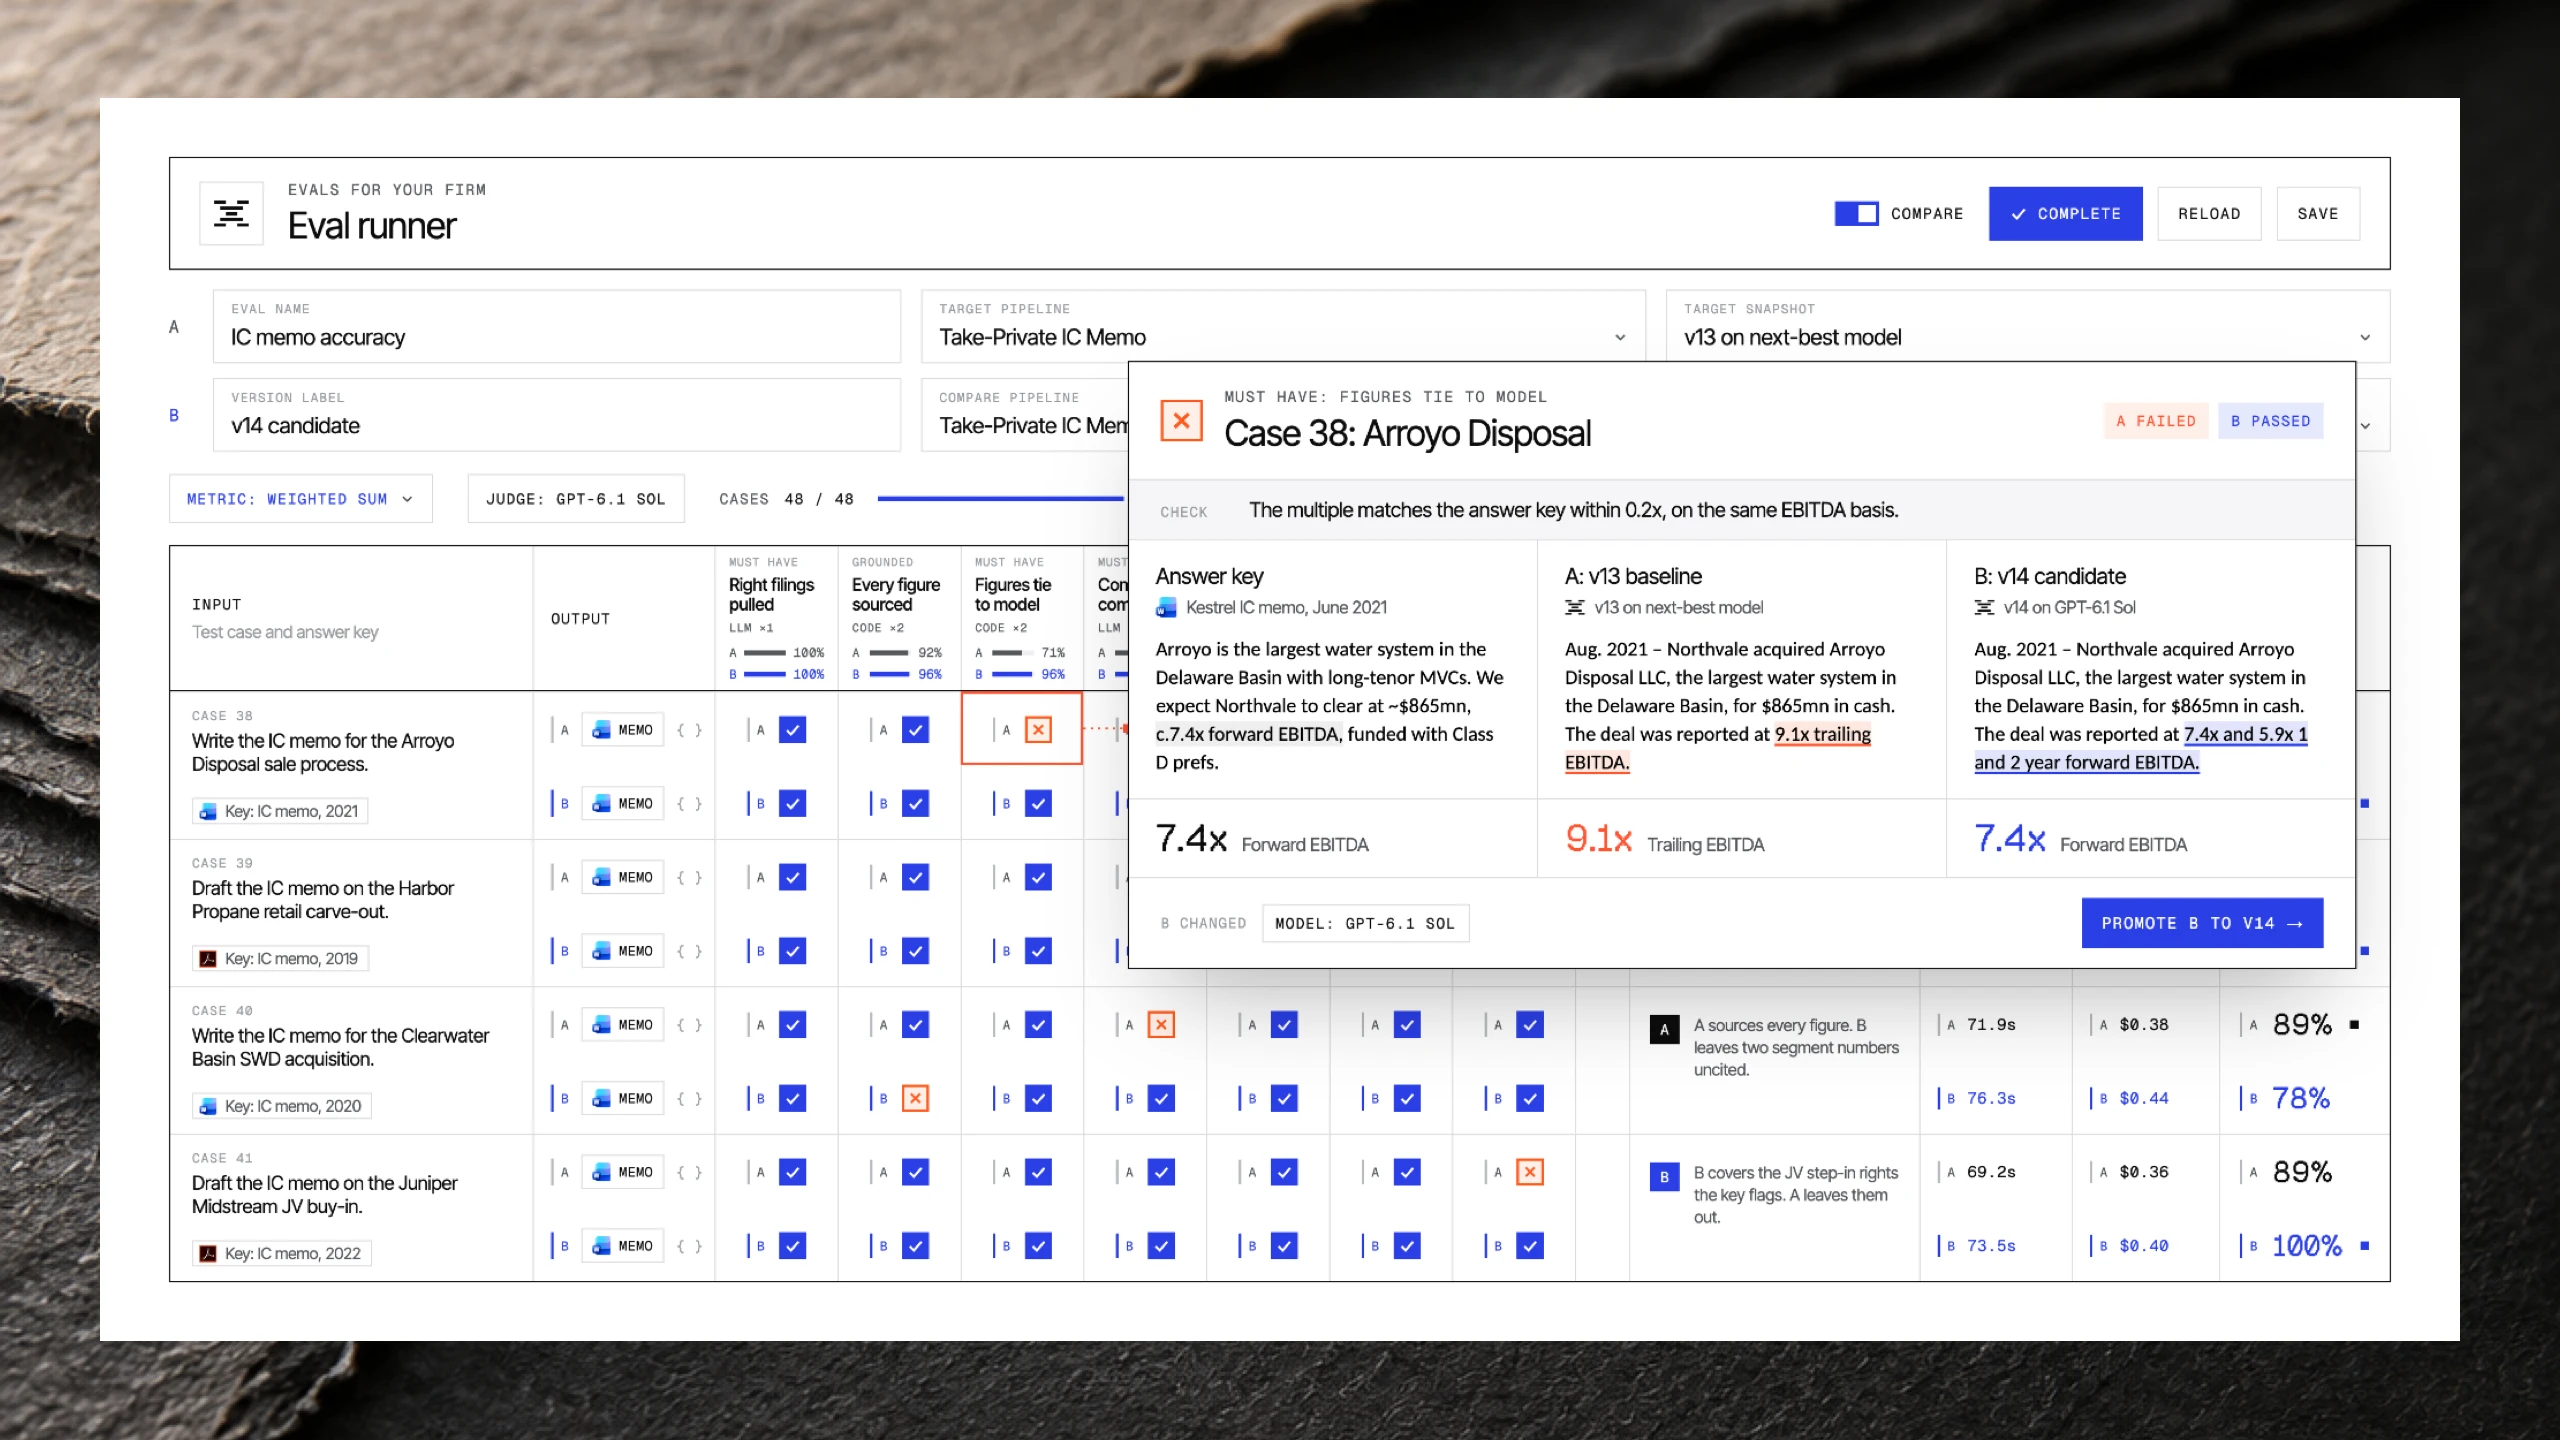
Each check scores pass or fail. Every fail includes a one-line reason and a better source or corrected text and becomes a Memory. For example, a missed source, a wrong comparable, or a thesis that drifts from the house view is encoded as a new workflow instruction or a new test case for that desk.
“Every answer gets eval’d, and whatever the analyst corrects teaches the system a little more about how that firm works,” says Ken Lee, Co-Founder and CTO of Terminal X. “So the longer a firm uses it, the more it thinks like their own team.”
Terminal X picks models based on its own evaluation results. Across 500 scored judgments, its Eval Agent on GPT‑6.1 Sol agreed with the senior human reviewer 88.6% of the time, vs. 86.4% for the next-best model, an improvement of 220 basis points.
One class of error where GPT‑6.1 Sol outperformed is style drift. For example, a buyout fund’s mandate is to find take-private candidates trading at a discount to NAV, underwrite the business, and structure the financing. When scenario models suggest a market turn, deals start recommending a distressed credit position or a rescue financing. The Eval Agent on GPT‑6.1 Sol caught about 25% more of these departures than the next-best model did.
GPT‑6.1 Sol’s token efficiency on long-context work enabled Terminal X to build a deeper review workflow within the same budget. The thesis is tested first against the fund’s mandate, then against its recent deals. Uncertain verdicts are re-run, and the agent reconciles the results before reporting.
That deeper review flagged deals that a single pass on a comparable model had waved through. GPT‑6.1 Sol also ran the same workflows at about 30% lower cost per query than the next-best model, at similar speed.
Using GPT‑6.1 Sol and GPT‑6 Luna, Terminal X has built 1,700 firm Memories, run more than 1 million custom workflows, and reached a weekly active user count equal to 81% of its monthly active users.
Terminal X’s next step is to extend firm Memories from desks to individuals, so that each investment professional’s standard is captured as it is practiced, not only as it is described.
For Hyun, co-founder and CEO of Terminal X, that is the point: “The firms that win the next decade will own their judgment as data. Our job is to make that judgment measurable, so it can be kept, improved, and reused.”